For most work, Opus 5.5 is now the best choice: it tops all three models on Anthropic’s published benchmarks at the lowest price. Fable 5.1 remains the pick for the hardest open-ended problems, and Opus 5 is mainly worth keeping for untested production pipelines.
Anthropic released these three frontier models in about two months: Opus 5 in July, Fable 5.1 in early September, and Opus 5.5 on September 22, 2026. This article covers what each model is, how they compare on performance and price, how their safeguards differ, and which fits which kind of work.
Disclosure: this article was written with Claude Opus 5.5, one of the models compared. It sticks to published numbers and notes where Anthropic itself says benchmarks overstate the differences.
The three models at a glance
All three share a 1 million token context window; they differ in tier, age and, above all, price.
| Model | Release | Tier | API model ID |
|---|---|---|---|
| Claude Opus 5.5 | September 22, 2026 | Opus | claude-opus-5-5 |
| Claude Fable 5.1 | September 2026 | Mythos-class (top tier) | claude-fable-5-1 |
| Claude Opus 5 | July 24, 2026 | Opus | claude-opus-5 |
Per token, Fable 5.1 costs 2.5x Opus 5.5 for input and output, while Opus 5.5 undercuts Opus 5 by 20% on every line and by 60% on cache reads.
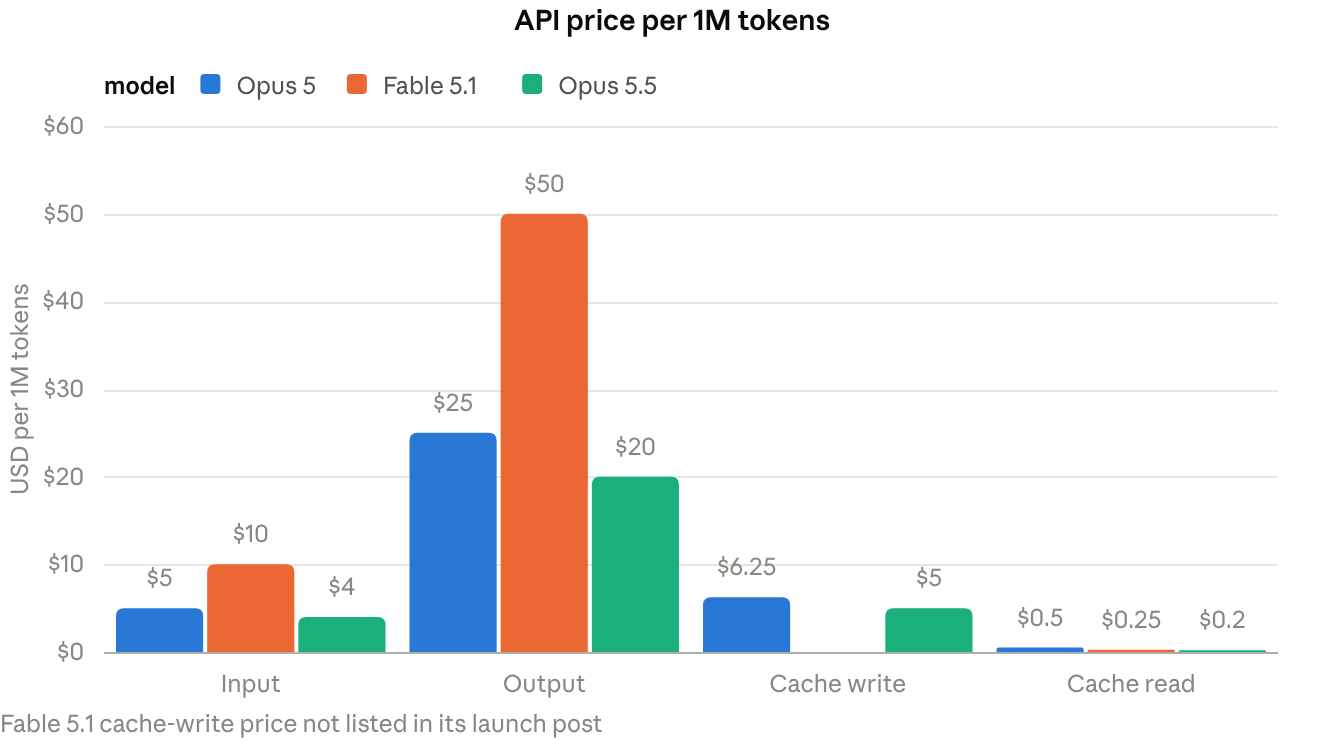
Anthropic launch posts for Opus 5.5 and Fable 5.1 · standard API rates
Claude Opus 5: the July flagship
Opus 5 brought near-Fable intelligence to Opus pricing. Anthropic pitched it as coming close to Fable 5 at half the price, at $5 input and $25 output per million tokens (DataNorth).
It shipped with 128k maximum output, adaptive thinking on by default, and new controls for effort, fallback and caching (CometAPI). Its standout result was ARC-AGI-3, a test of novel problem solving, where it scored three times the next best model (gori.me).
Its weak spots showed up later. Writing clarity was one of the most common complaints, and in side-by-side tests Opus 5 used more tokens and steps than both successors (Anthropic).
Claude Fable 5.1: the Mythos-class model
Fable 5.1 is Anthropic’s most capable generally available model for long, hard, open-ended problems. It is the same underlying model as Mythos 5.1, which has looser safeguards and is limited to trusted access programs (Anthropic).
Its strength is persistence and depth:
- Debugging: at the investment firm Millennium, it found the cause of a rare crash that engineers and other models had failed to explain for years.
- Science: it trained a neural network that mapped about a third of Venus in high resolution from decades-old Magellan radar data.
- Biology (Mythos 5.1): it designed protein binders with a hit rate near 50% across 12 targets, against a typical 10–15%.
The 5.1 update also answered complaints about Fable 5. Cache reads became 75% cheaper, cutting typical costs by about 25% and agentic costs by up to 45%. Cyber safeguards now trigger about 60% less often per Claude Code session, and the model may find vulnerabilities but not build exploits.
Against Opus 5, early testers at Every reported it ran about twice as fast and used half the tokens.
Claude Opus 5.5: the new all-rounder
Opus 5.5 delivers Fable-class results at Opus pricing. It is the first Claude 5.5 model, and Anthropic says it matches Fable 5.1 on most work while costing 40% less to run than Opus 5 (Anthropic).
It also generates output more than 30% faster than Opus 5. A fast mode in Claude Code and the Claude Platform reaches up to 2.5x speed at $8 input and $40 output per million tokens.
Anthropic’s examples compare it with both rivals:
- Codebase audit: one tester audited and fixed a 200,000-line codebase in under three hours; Opus 5 took over 20 hours and 2.5x the tokens.
- C-to-Rust port: both Opus 5.5 and Fable 5.1 rewrote HAProxy and passed nearly all its regression tests. Opus 5.5 took 9.5 hours versus 12, at 51% lower cost.
- Sourced research: writing earnings reports where any invented figure failed, Opus 5.5 passed 16 of 18 attempts. Fable 5.1 and Opus 5 passed none.
Sonnet 5.5 and Haiku 5.5 are due in the coming weeks.
Head-to-head benchmarks
Opus 5.5 leads on every benchmark Anthropic published, and Opus 5 trails on every one. These scores come from the Opus 5.5 launch post, the only source testing all three side by side.
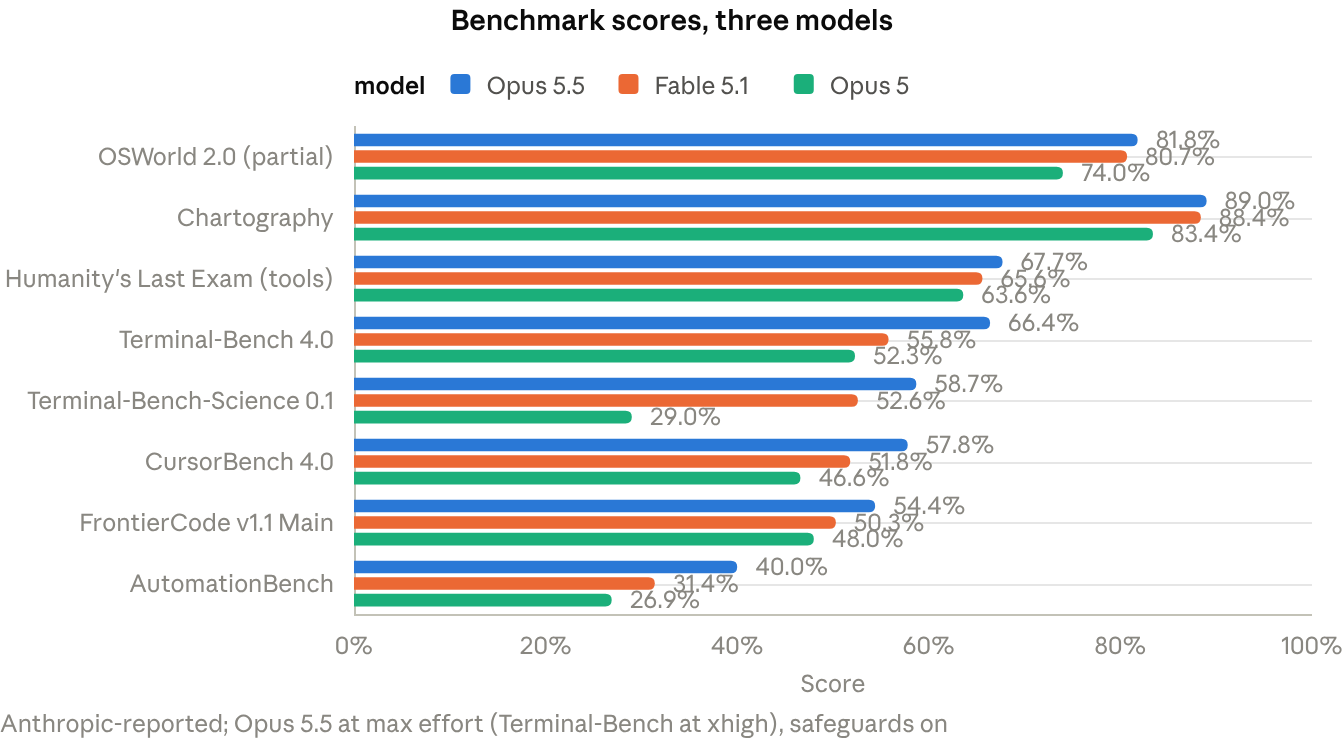
Anthropic, Introducing Claude Opus 5.5 · 8 benchmarks
On GDPval-AA v2.1, a knowledge-work test across 44 occupations, the Elo scores follow the same order: Opus 5.5 at 1846, Fable 5.1 at 1735 and Opus 5 at 1708. The widest gap is agentic science, where Opus 5 scores 29% and both newer models exceed 50%.
Two caveats apply. Anthropic says that at this capability level, benchmark margins are a weaker guide to real-world differences, and the Opus 5.5–Fable 5.1 gap is narrower in its own use. The Fable 5.1 launch post also used older benchmark versions, so its numbers differ; there, Fable 5.1 beat Opus 5 on every test.
Cost: where the models differ most
Opus 5.5 is the cheapest per task by a wide margin. It costs less per token than both rivals and also uses fewer tokens to finish a job, which Anthropic says nets out to about 40% below Opus 5.
Fable 5.1 is the priciest. Cursor’s documentation notes its rates run about 2.5x Opus 5.5’s, while Opus 5.5 now scores higher on CursorBench.
Opus 5.5 defaults to medium effort. At that default it scores 52.5% on CursorBench, above Fable 5.1 (51.8%) and Opus 5 (46.6%) at max effort. If your prompts and effort levels were tuned for Opus 5, measure cost per completed task on your own workload before counting on the full 40%.
Safety, alignment and safeguards
Opus 5.5 has the strongest published alignment results but tighter guardrails than earlier Opus models; Fable 5.1 adds an enterprise privacy option; Opus 5 is the least restricted.
| Model | Alignment | Safeguards | Notes |
|---|---|---|---|
| Opus 5.5 | Best recent Claude score on nearly every misalignment measure across ~2,000 scenarios; ~85% fewer boundary-circumvention attempts than Opus 5 or Mythos 5.1 | First Opus with Fable-class cyber, biology and distillation safeguards; most cyber tasks reroute to Opus 4.8 | Thinking cannot be switched off; often suspects it is being evaluated |
| Fable 5.1 | Mythos 5.1 better aligned than Mythos 5 on most metrics | Cyber interventions ~60% lower than Fable 5; bug-finding allowed, exploits not | Enterprise Frontier Safeguards keep data on customer cloud; Mythos 5.1 via verification programs |
| Opus 5 | Earlier baseline | Lighter: allows finding and fixing vulnerabilities, blocks high-risk uses | Stronger than Opus 4.8 at cyber, well behind Mythos 5 at exploits |
Sources: Opus 5.5 launch, Fable 5.1 launch, gori.me on Opus 5.
Teams that used Opus 5 for security research may find Opus 5.5 more restrictive in practice.
Which model should you use?
flowchart TD
A[New task] –> B{Stumped other models,<br/>or needs Mythos bio/cyber?}
B — Yes –> F[Fable 5.1]
B — No –> C{Untested Opus 5<br/>pipeline in production?}
C — Yes –> O[Keep Opus 5 until re-tested]
C — No –> N[Opus 5.5]
Start at the top and follow your answers; most tasks end at Opus 5.5.
- Opus 5.5 for most work. Best published scores, lowest price, fastest output and clearer writing make it the default for coding agents, research reports and business automation.
- Fable 5.1 for the hardest open-ended problems. Anthropic’s own caveat implies Fable still wins some tasks, such as multi-day autonomous runs and frontier science. It is also the route to Mythos-level capability through verification programs.
- Opus 5 only with a reason. Keep it for pipelines you have not re-tested, or behavior that relies on its lighter safeguards or on disabling thinking. Opus 5.5 changes some API behavior, so test before switching.
The bottom line
Start with Opus 5.5 and move up to Fable 5.1 only when a task clearly needs it. Each launch shifted where the value sits: Opus 5 brought near-Fable performance to Opus prices, Fable 5.1 raised the ceiling and cut its own costs, and Opus 5.5 now beats Fable 5.1 on benchmarks at 40% of its per-token price. With Sonnet 5.5 and Haiku 5.5 due within weeks, this comparison will keep moving.
Sources
- Introducing Claude Opus 5.5 — Anthropic
- Introducing Claude Fable 5.1 and Claude Mythos 5.1 — Anthropic
- Claude Fable 5.1 — Cursor Docs
- Claude Opus 5 by Anthropic: benchmarks & pricing — DataNorth
- Claude Opus 5 API overview — CometAPI
- Claude Opus 5 launch coverage — gori.me
Last Updated on November 8, 2026 by Logan Carter
Comments